
A vLLM Deep Dive: Distributed Inference, KV Cache Evolution, and Model Compression
Tokyo vLLM Community Night: five deep-dive talks on distributed inference, KV cache, model compression, and production serving.
- When
- Where
- Minato City, Tokyo·In person
- Region
- Kanto (Tokyo)
- Organizer
- Tokyo AI
- Language
- EN
- Source
- Luma
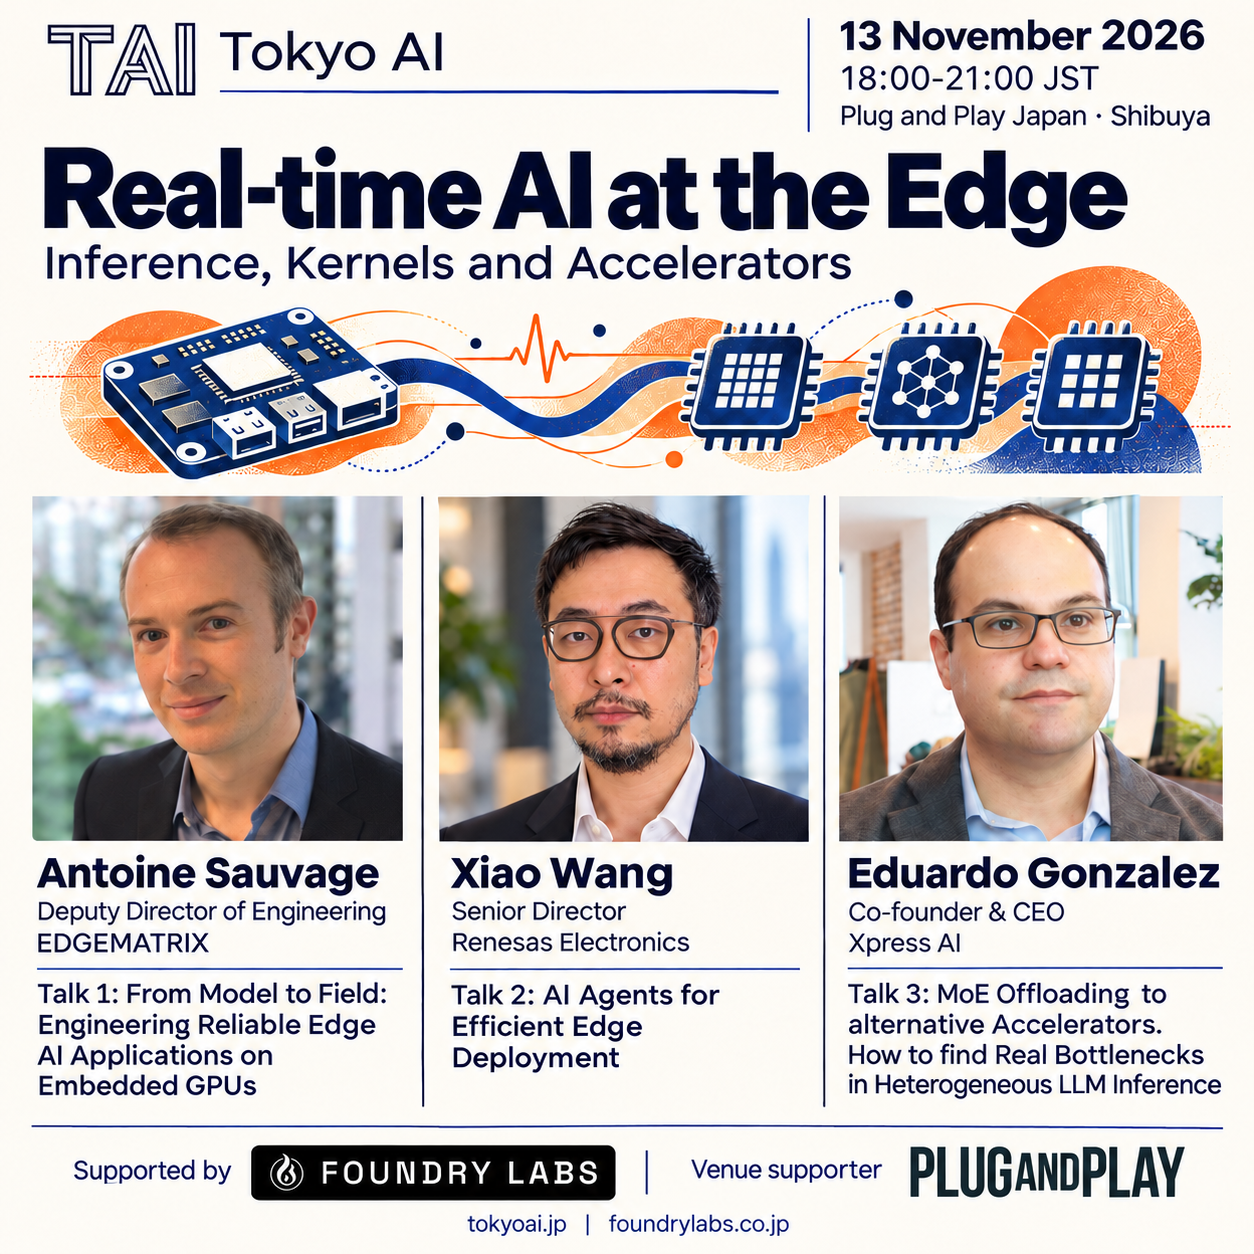
Next from Tokyo AI
Similar upcoming events
Tokyo Python: Around the World in 80 Dags
Jarek Potiuk on Apache Magpie, agent skills that help open-source maintainers handle AI-generated PRs and reports, plus an Airflow intro.

How to train your own LLM 🧑💻 & networking 🤝
Talk and live demo in Shibuya on fine-tuning and compressing your own lightweight LLM to run offline, followed by networking.

Tech Brunch Event
Brunch meetup at a Iidabashi hotel for sharing open source experiences, projects, licensing and community topics.

Summary
About the community
Organized by Ilya Kulyatin (Tokyo AI / Foundry Labs) and Jiaqi Lim (Embedded LLM), hosted by Tokyo AI (TAI) — Japan's largest AI community with 4,000+ members — together with Embedded LLM, an AI infrastructure company and leading vLLM contributor that also builds the TokenVisor platform for metered, governed GPU services.